/PROJECT · complete
AI-Powered E-Consultation Suite
Sentiment, key phrases and summaries for public comments on government consultations.
On this page
Overview
Ministries and organizations that run public consultations can receive thousands of comments. Reading them by hand is slow and subjective. This project gives a reviewer a quick read on the overall mood of the feedback and a short summary of long submissions.
How it works
The app has three pages: a dashboard, Sentiment Analysis, and Smart Summaries, switched through a sidebar menu and Streamlit session state.
On the sentiment page, the input is either pasted text (one comment per line) or a URL. For a URL, a headless Chromium browser driven by Playwright loads the page and keeps every paragraph longer than eight words. Each comment goes through cardiffnlp/twitter-roberta-base-sentiment-latest, and the softmax scores are averaged across comments to give an overall label and a confidence figure. A scikit-learn CountVectorizer extracts the top five words and two-word phrases, and the results are shown with a Plotly bar chart and a word cloud.
The summary page runs sshleifer/distilbart-cnn-12-6 on CPU for text over 40 words. Minimum and maximum length are set with sliders, and the page reports original and summary word counts.
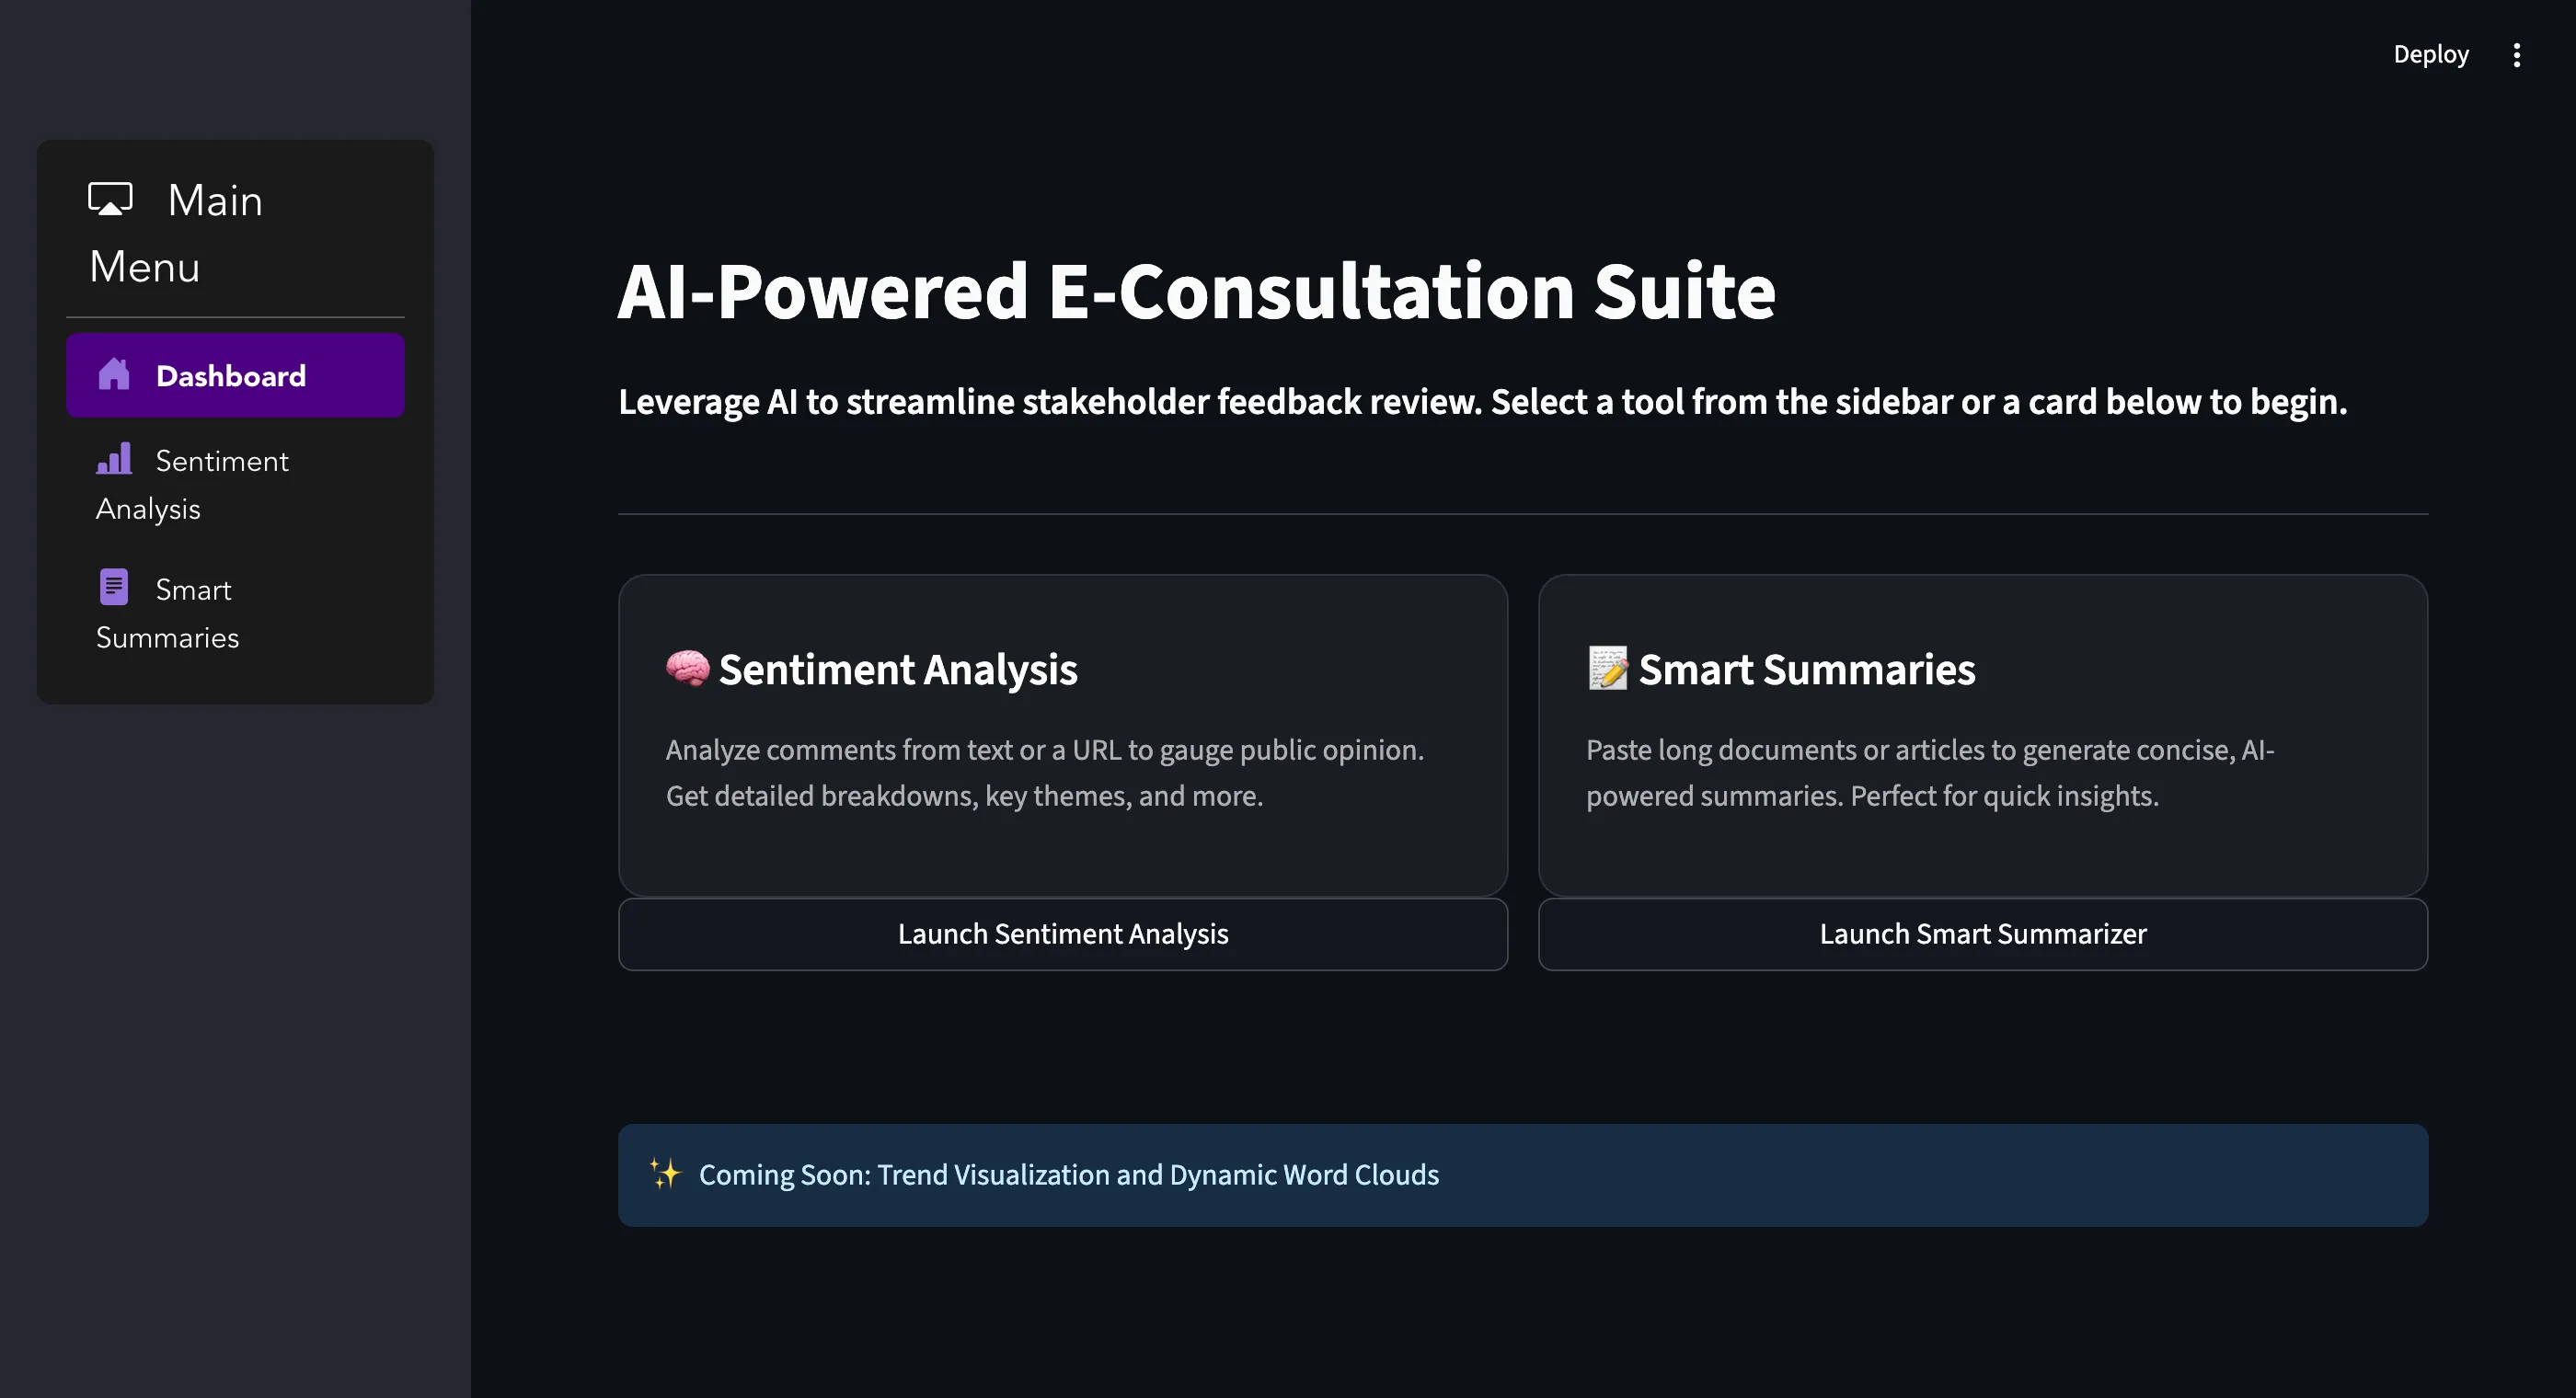
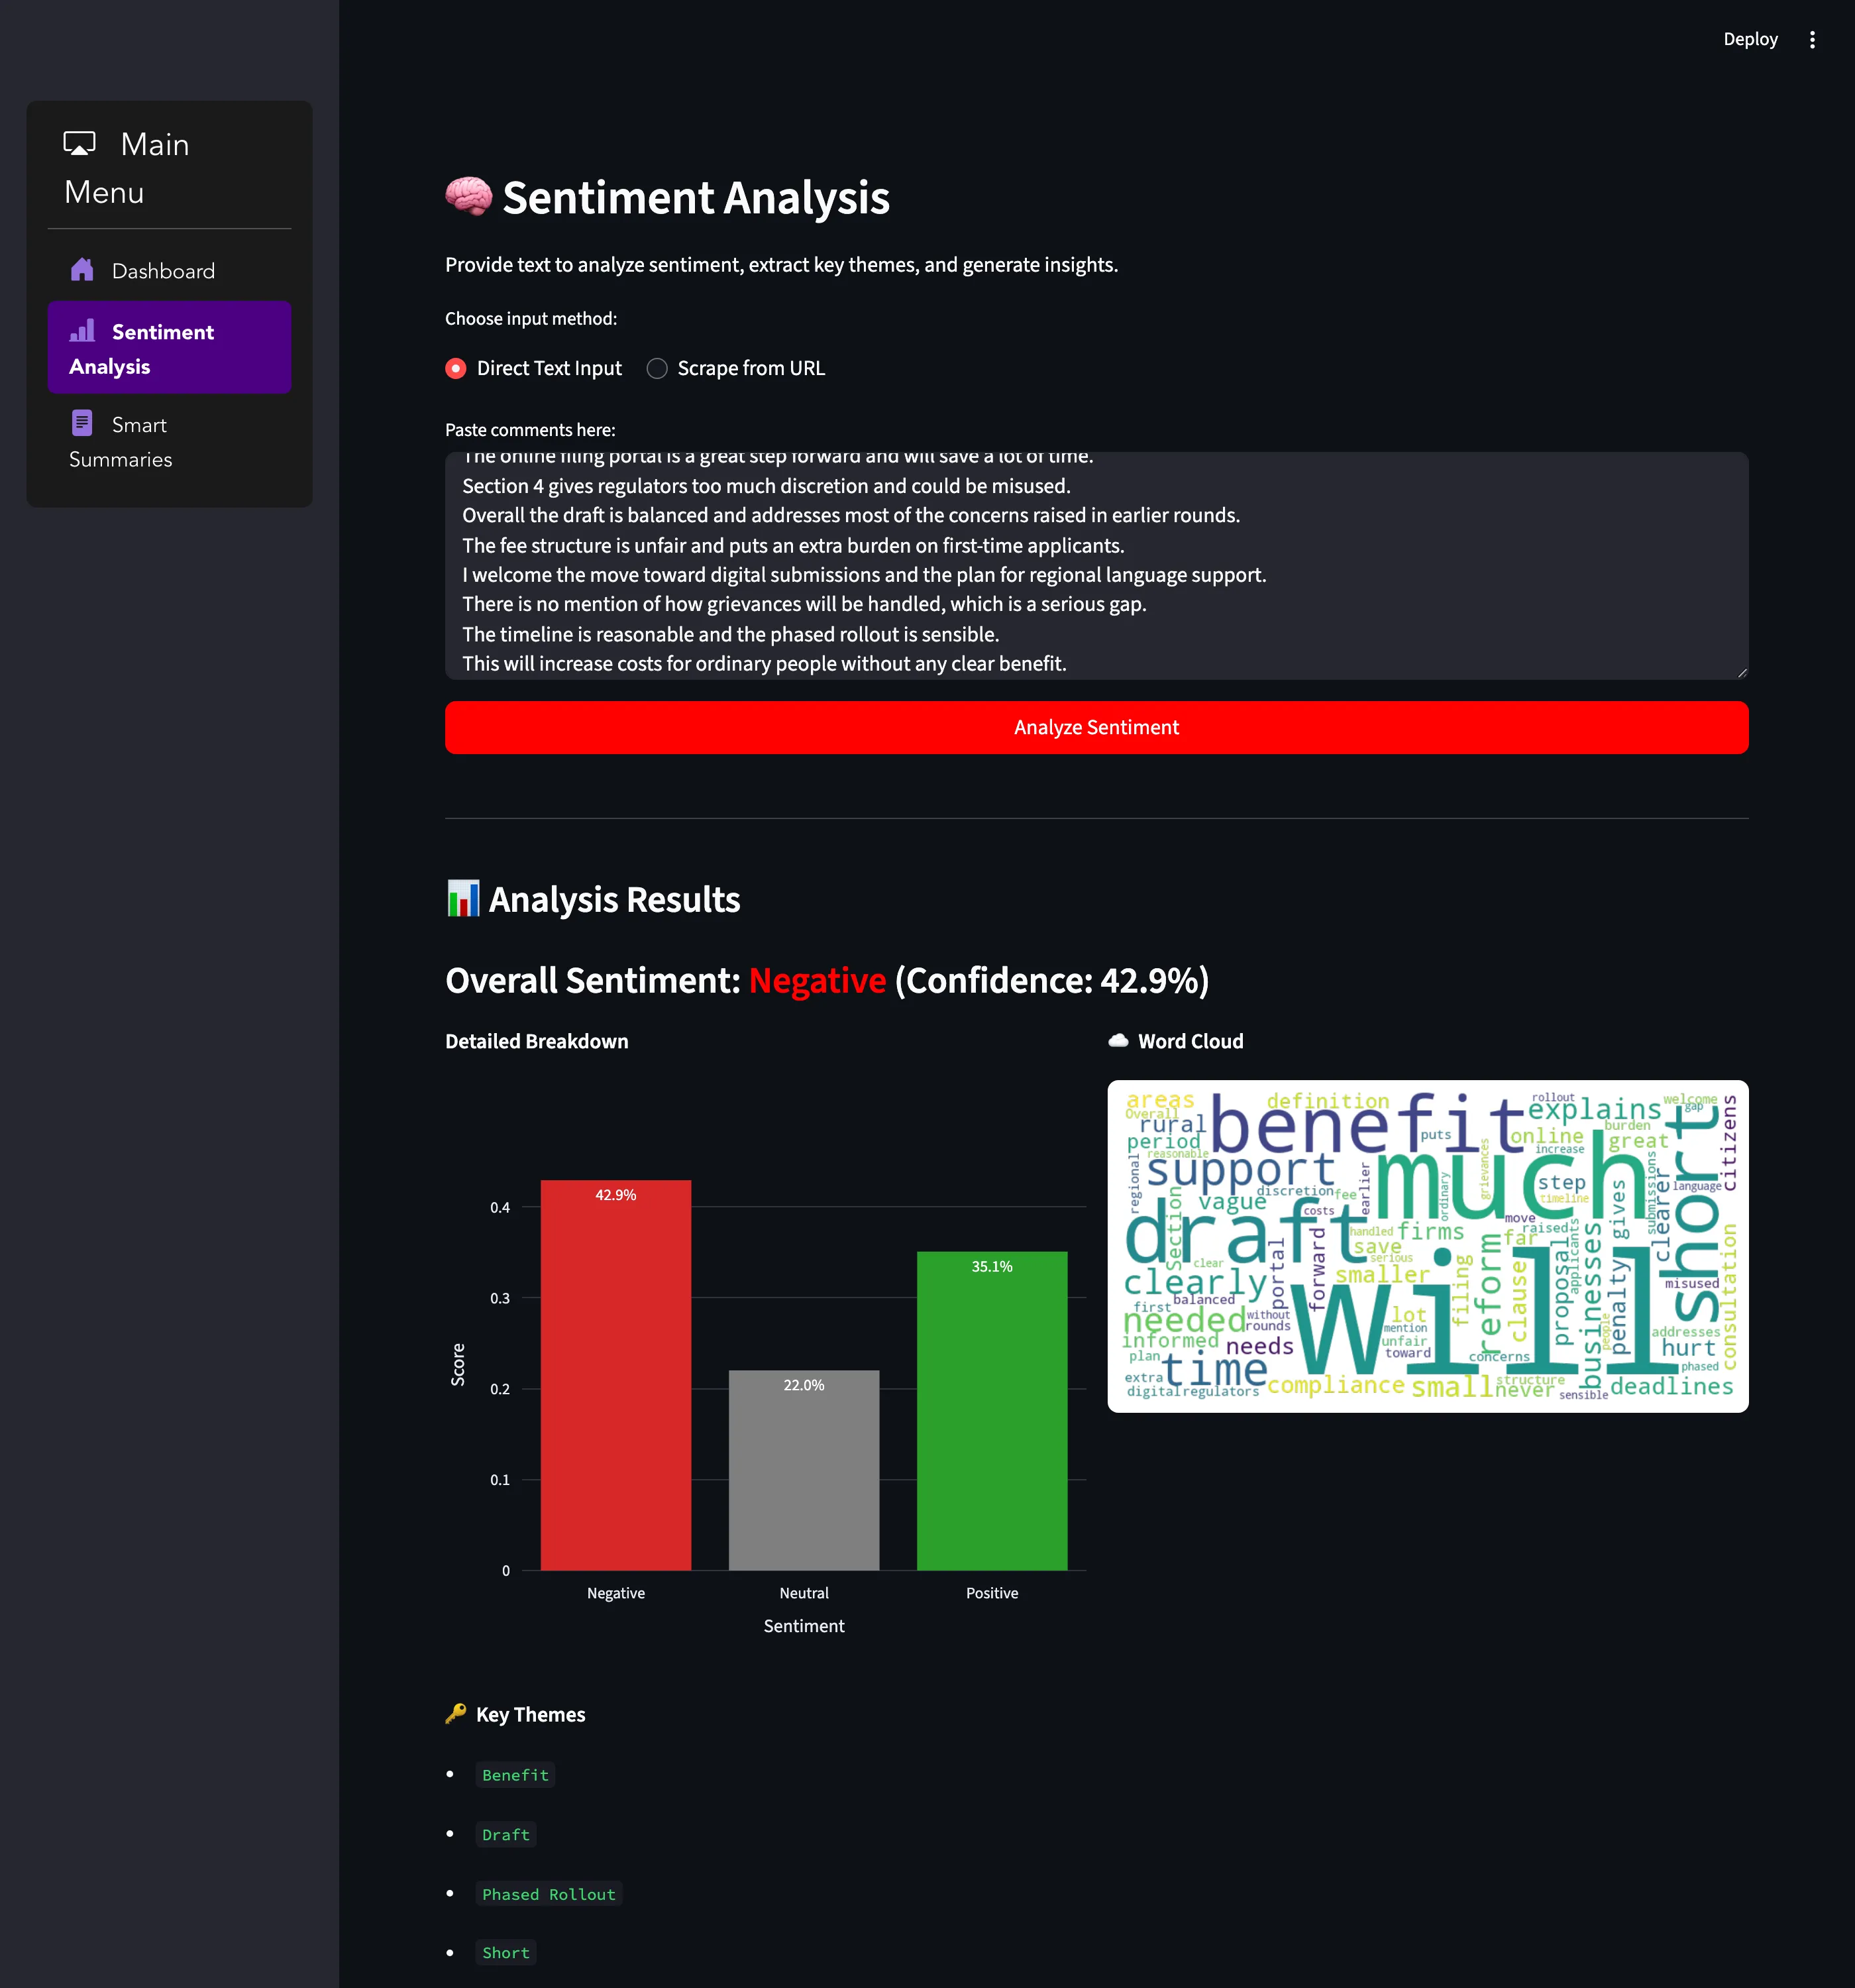
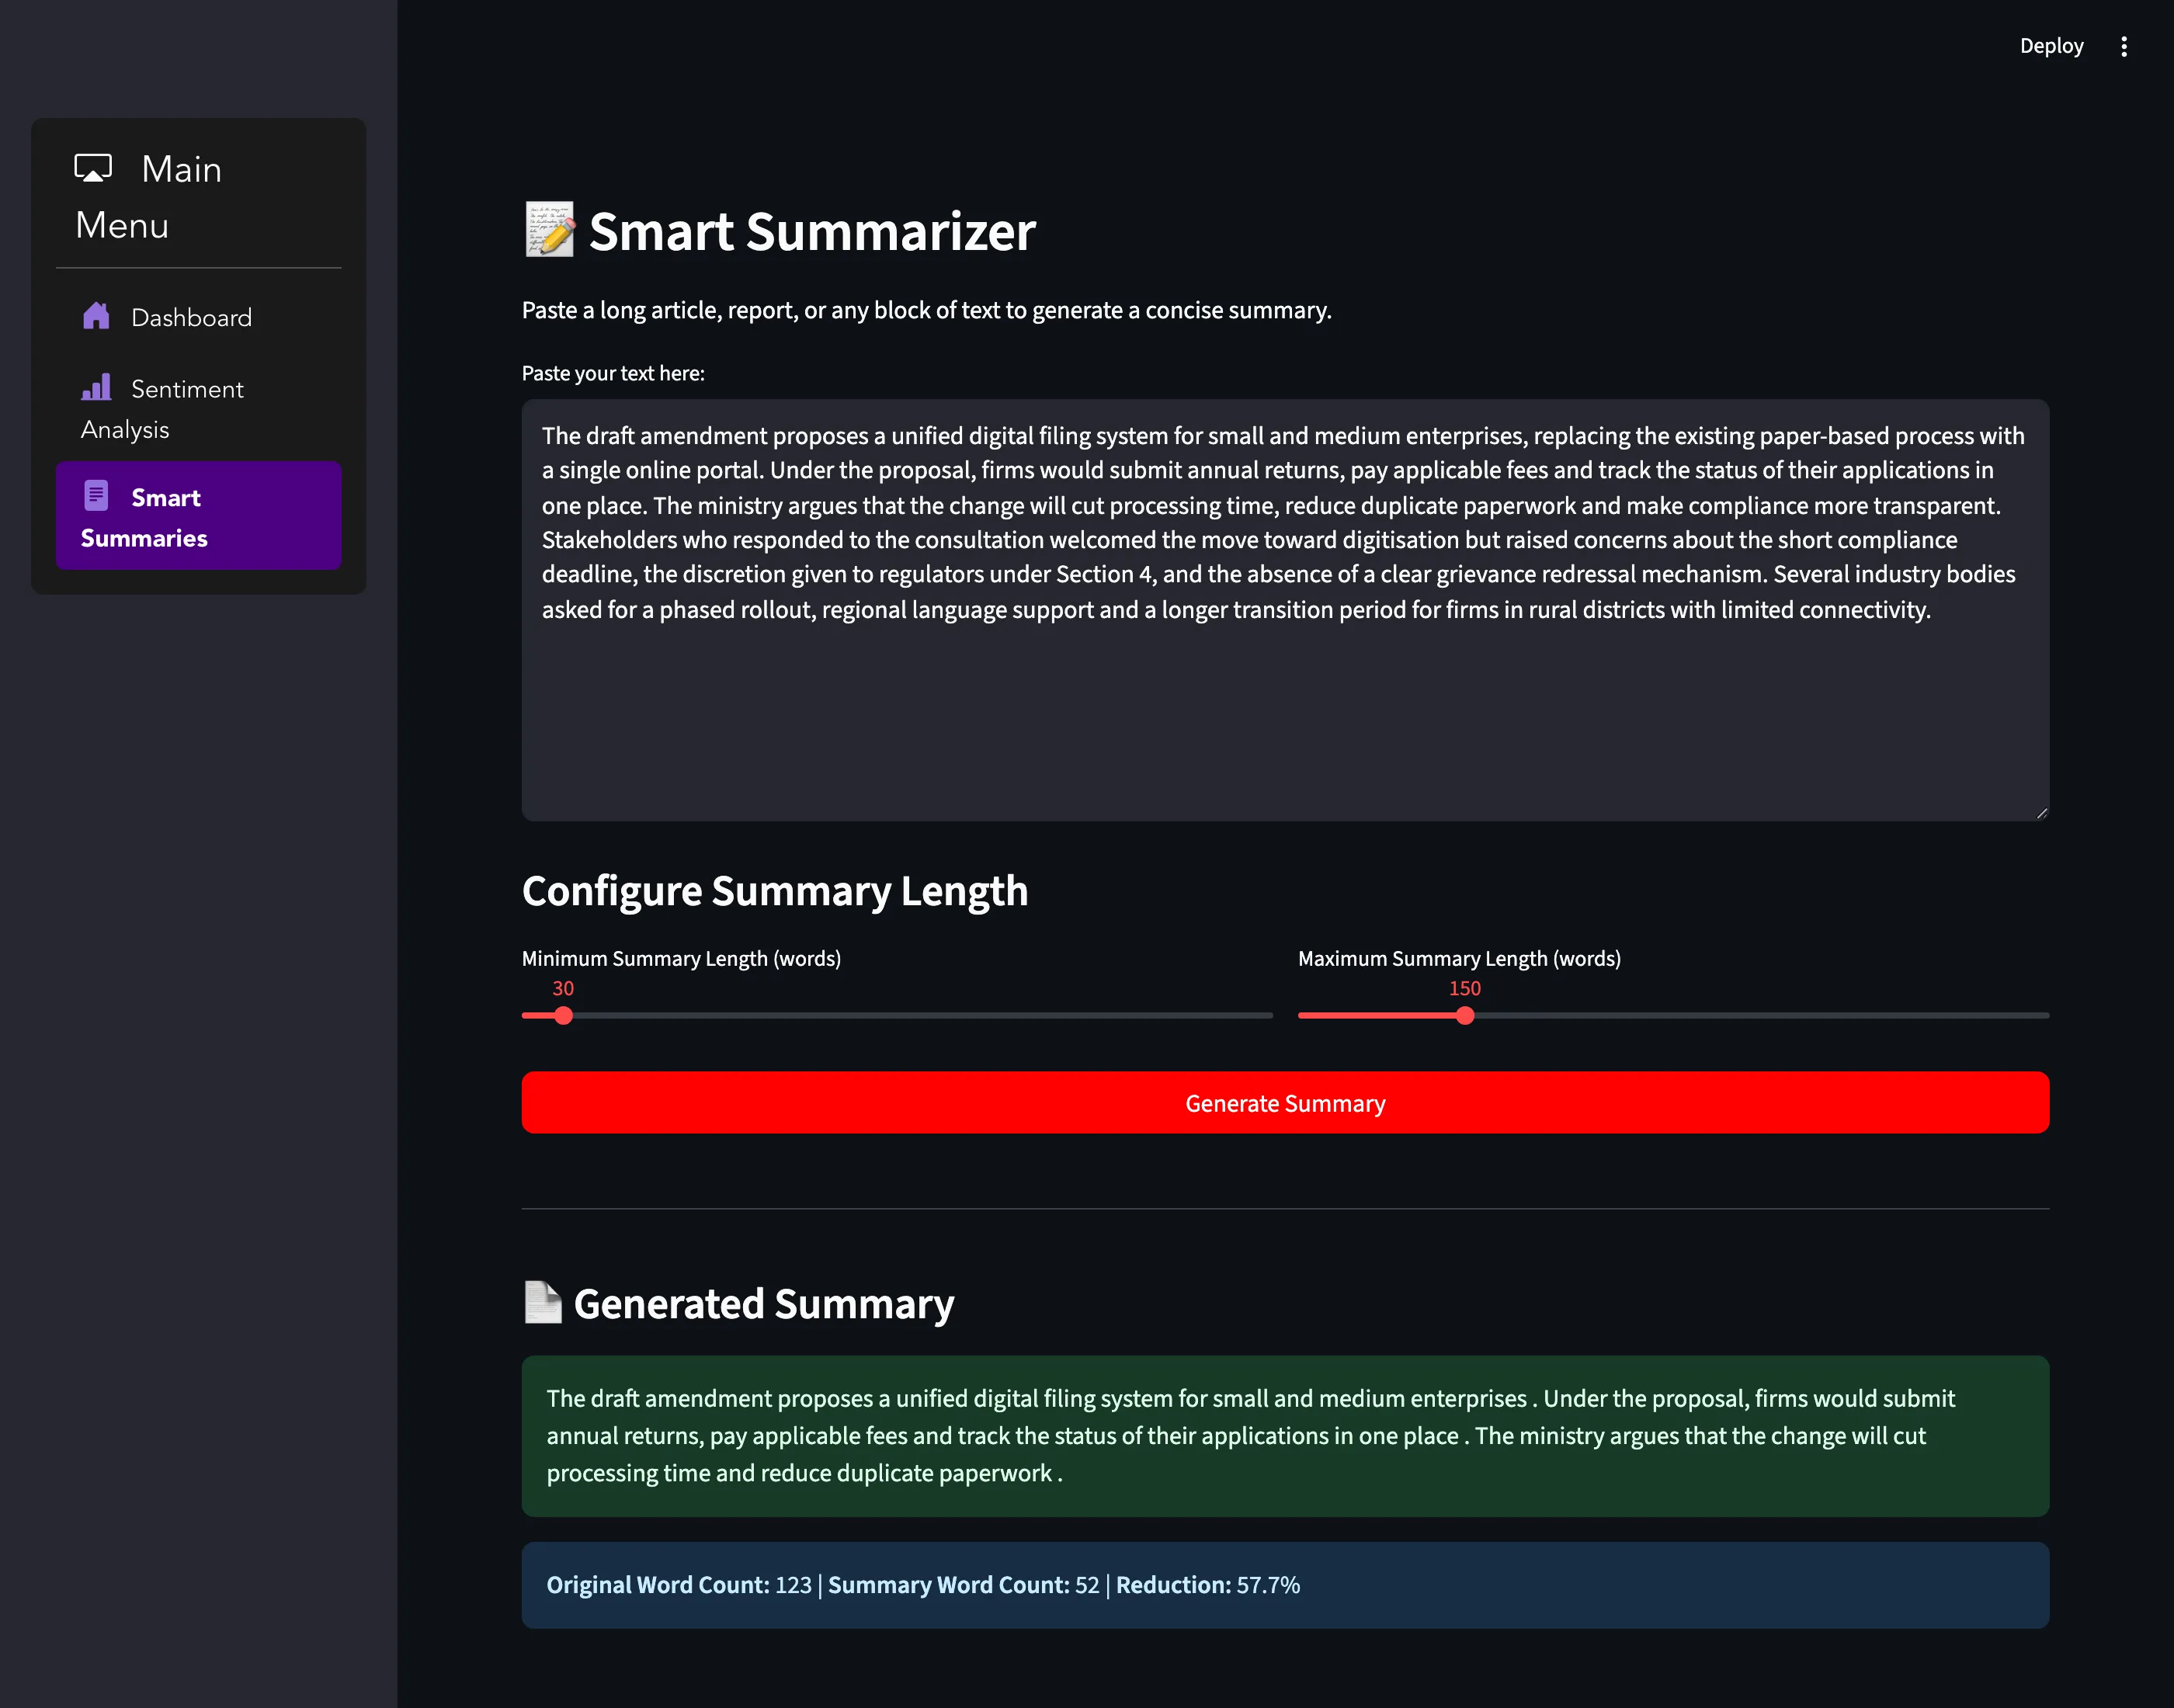
The screenshots use made-up sample text, not real consultation data.
sentiment: cardiffnlp/twitter-roberta-base-sentiment-latest
summarizer: sshleifer/distilbart-cnn-12-6
input: pasted comments or a URL (Playwright, headless Chromium)
runs_on: CPU
Where it could break
[TODO: no risks written for this project yet]
Key features
- Three-class sentiment scoring with an overall confidence figure
- Comment input by pasting text or scraping a URL
- Key phrases and a word cloud
- Abstractive summaries with adjustable length
- Models load only when the page that needs them is opened
Highlights
- Built a three-page Streamlit app with sidebar navigation and session-state routing in a single 223-line
app.py. - Integrated a Hugging Face RoBERTa sentiment model and averaged per-comment softmax scores into an overall label with confidence.
- Wrote a Playwright scraper that extracts paragraphs from a URL and handles timeouts and page errors.
- Added DistilBART summarization with user-set length limits and a word-count reduction readout.
- Refactored model loading into per-page
st.cache_resourceloaders to cut startup memory use.
Tech stack
- Language: Python
- App framework: Streamlit, streamlit-option-menu
- ML / NLP: PyTorch, Hugging Face Transformers (RoBERTa, DistilBART), scikit-learn
- Data and visualization: Pandas, NumPy, Plotly, Matplotlib, WordCloud
- Scraping: Playwright (headless Chromium)
- Deployment: none configured
- Tooling: pip with
requirements.txt, Git and GitHub
/Stack
- Python
- Streamlit
- PyTorch
- Hugging Face Transformers
- scikit-learn
- Pandas
- NumPy
- Plotly
- Matplotlib
- WordCloud
- Playwright
- streamlit-option-menu